Publications
A complete citation record is available on Google Scholar.
Research
Selected publications
Don't be lazy: CompleteP enables compute-efficient deep transformers
We introduce CompleteP, a parameterization that transfers hyperparameters across depth while keeping every layer in a non-lazy learning regime, improving training compute efficiency by 12-34%.
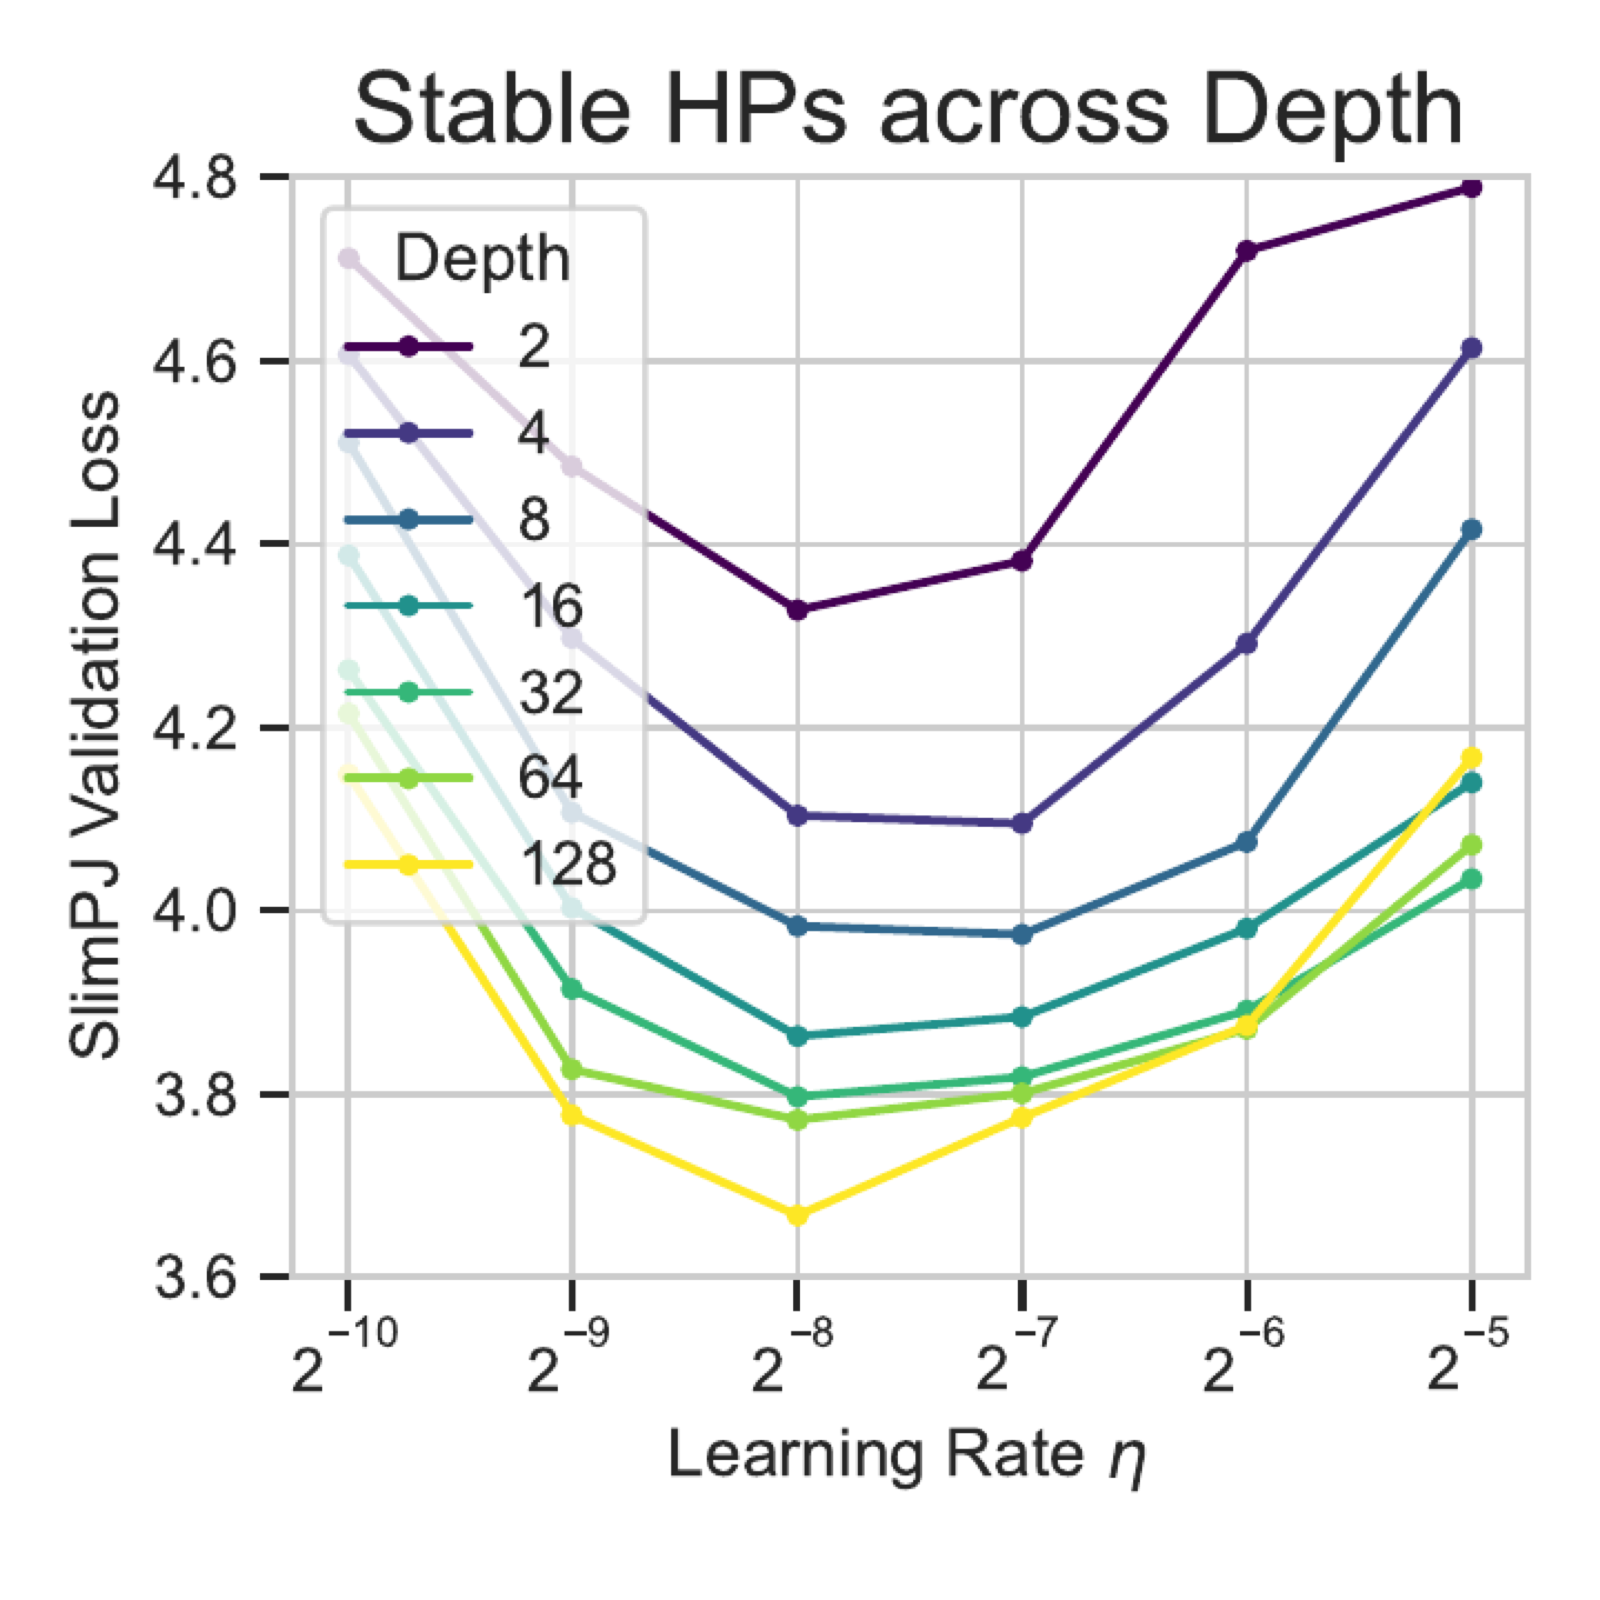
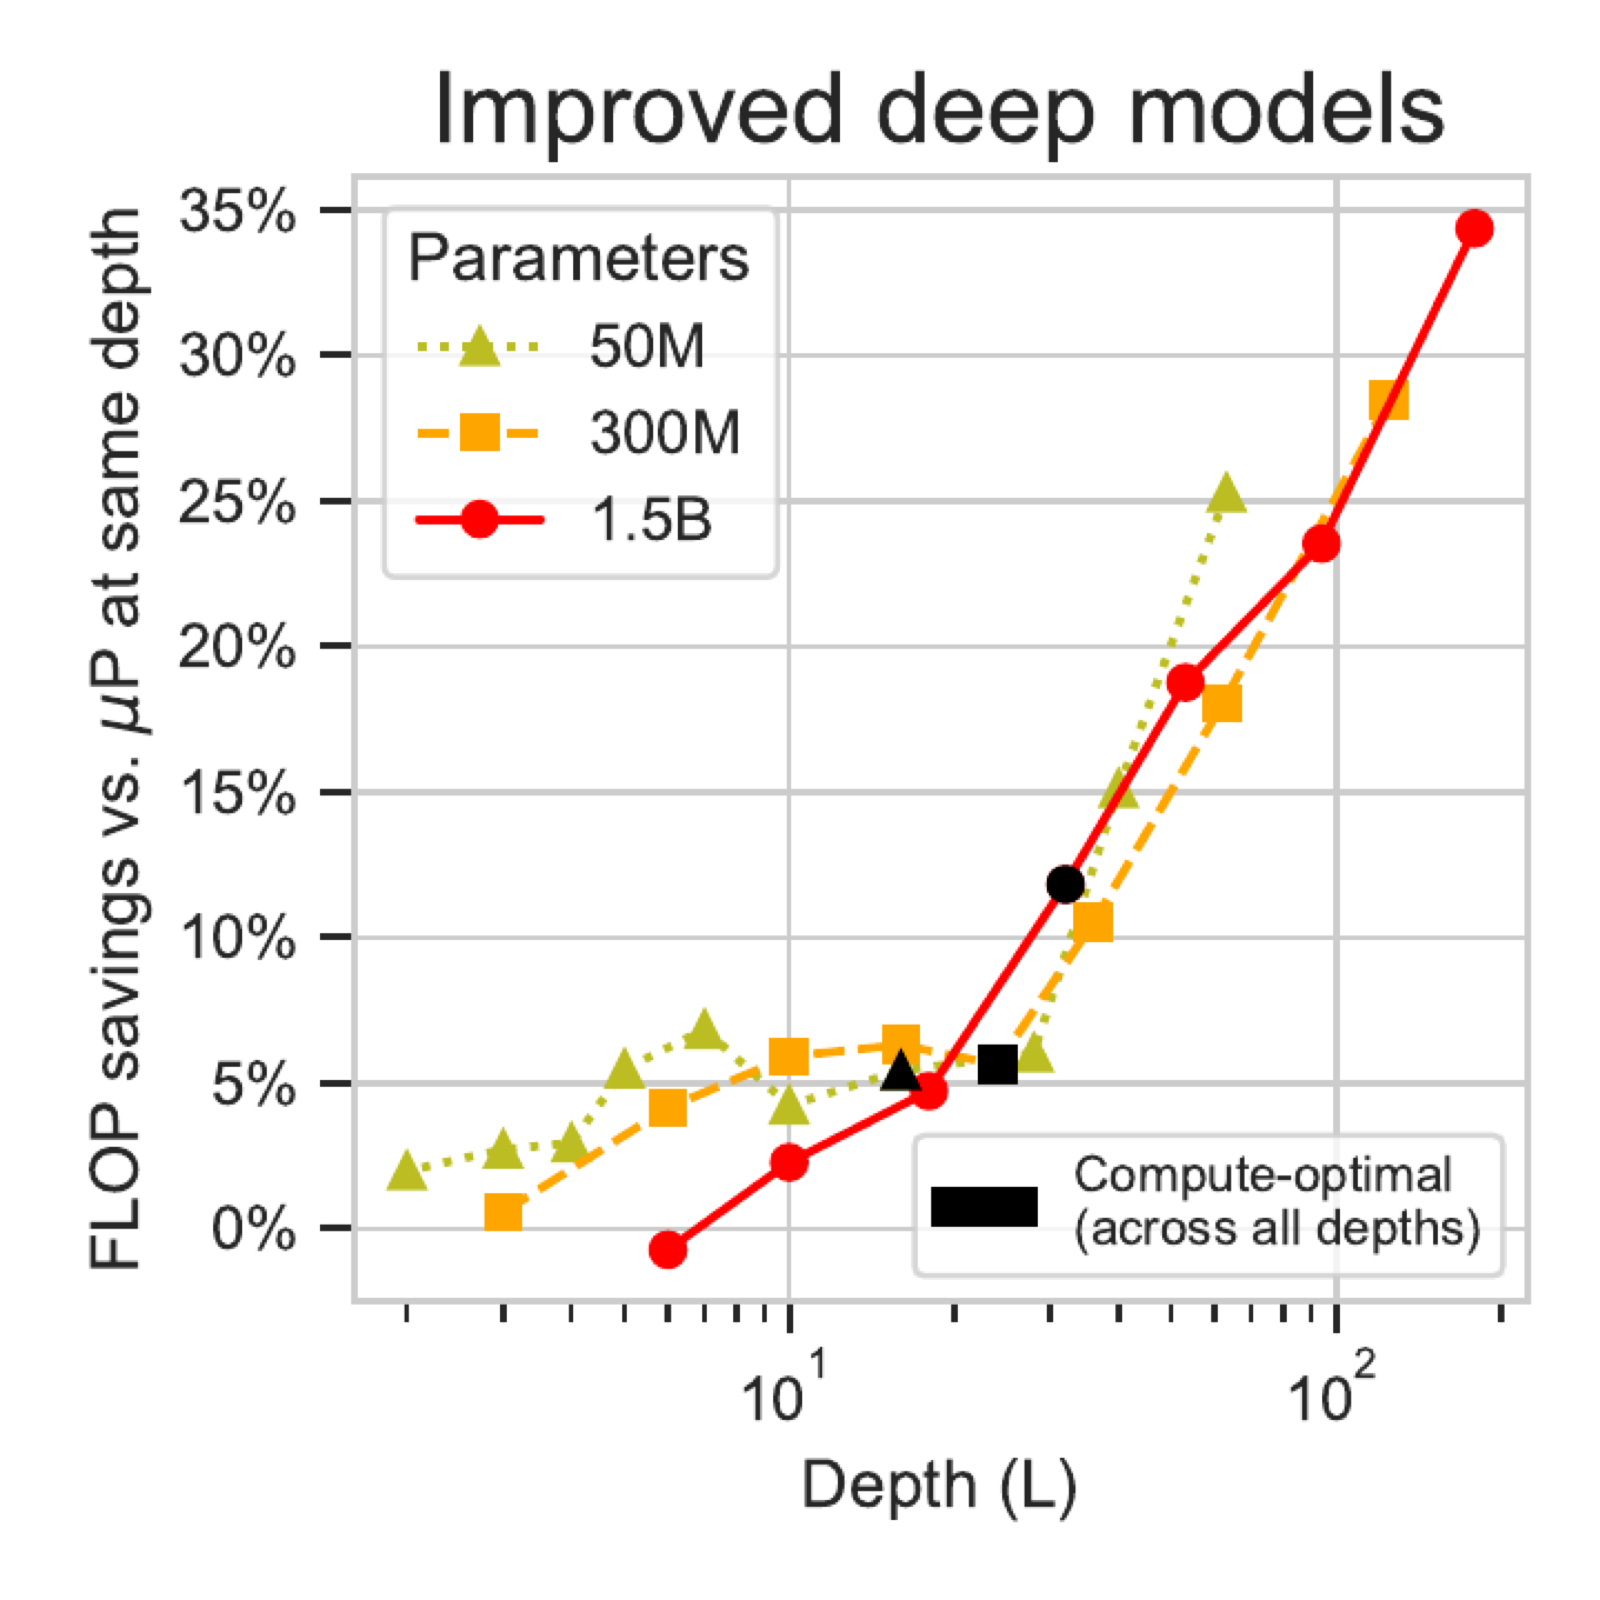 Figure 1
Understanding and Minimising Outlier Features in Neural Network Training
We study why activation outliers emerge during transformer training and show how architectural and optimization choices can substantially reduce them without slowing convergence.
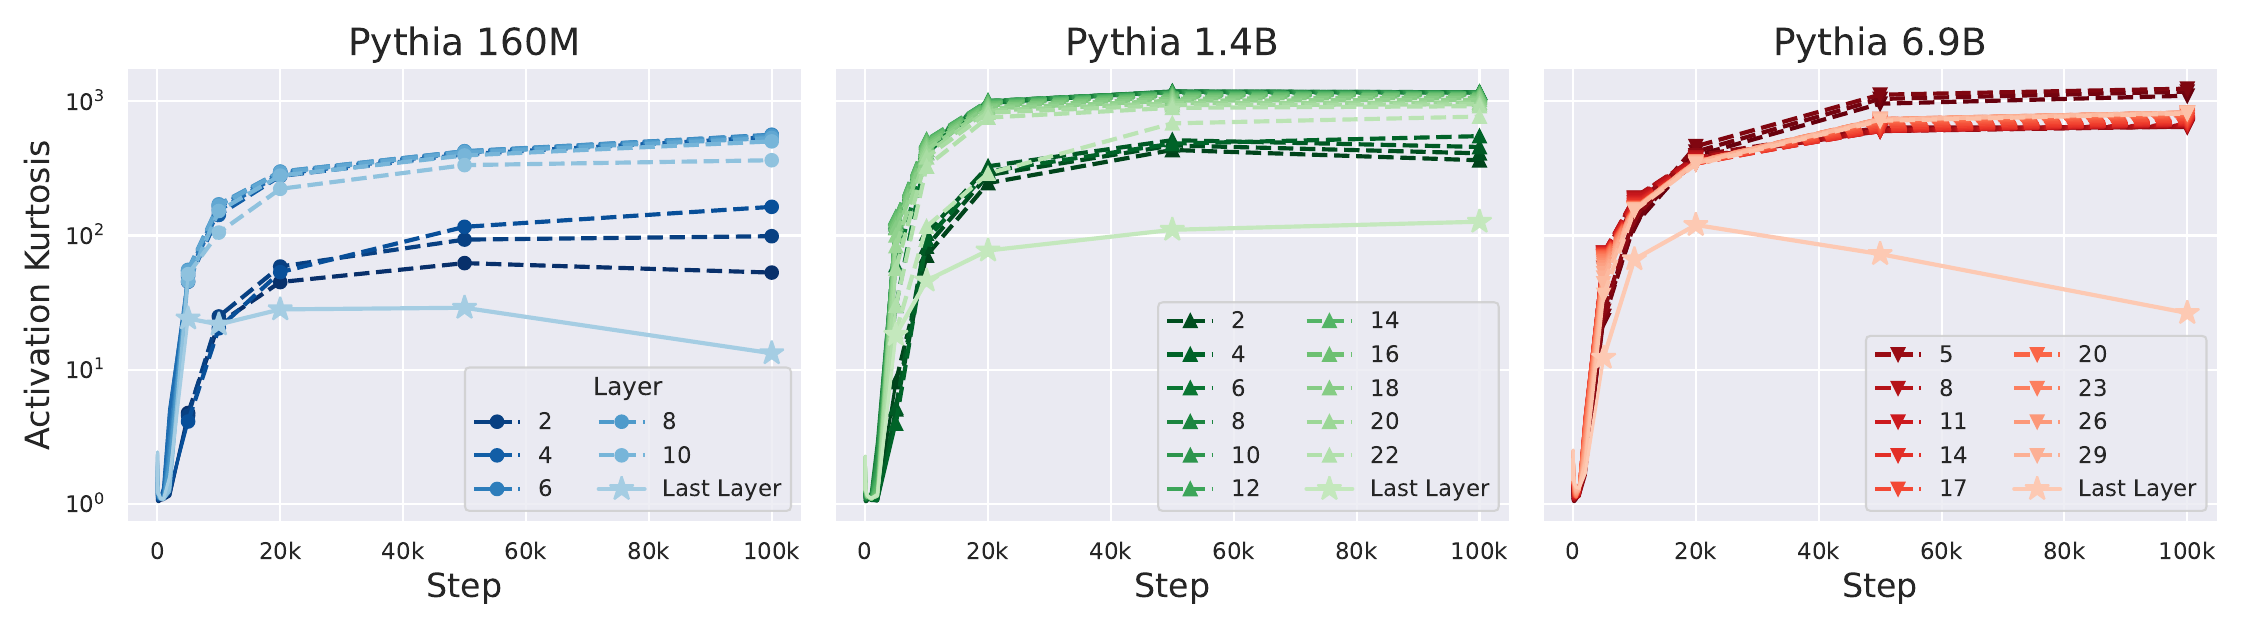 Figure 1
Super Consistency of Neural Network Landscapes and Learning Rate Transfer
We find that neural-network loss landscapes can remain remarkably consistent across width, explaining when learning rates transfer from small models to larger ones.
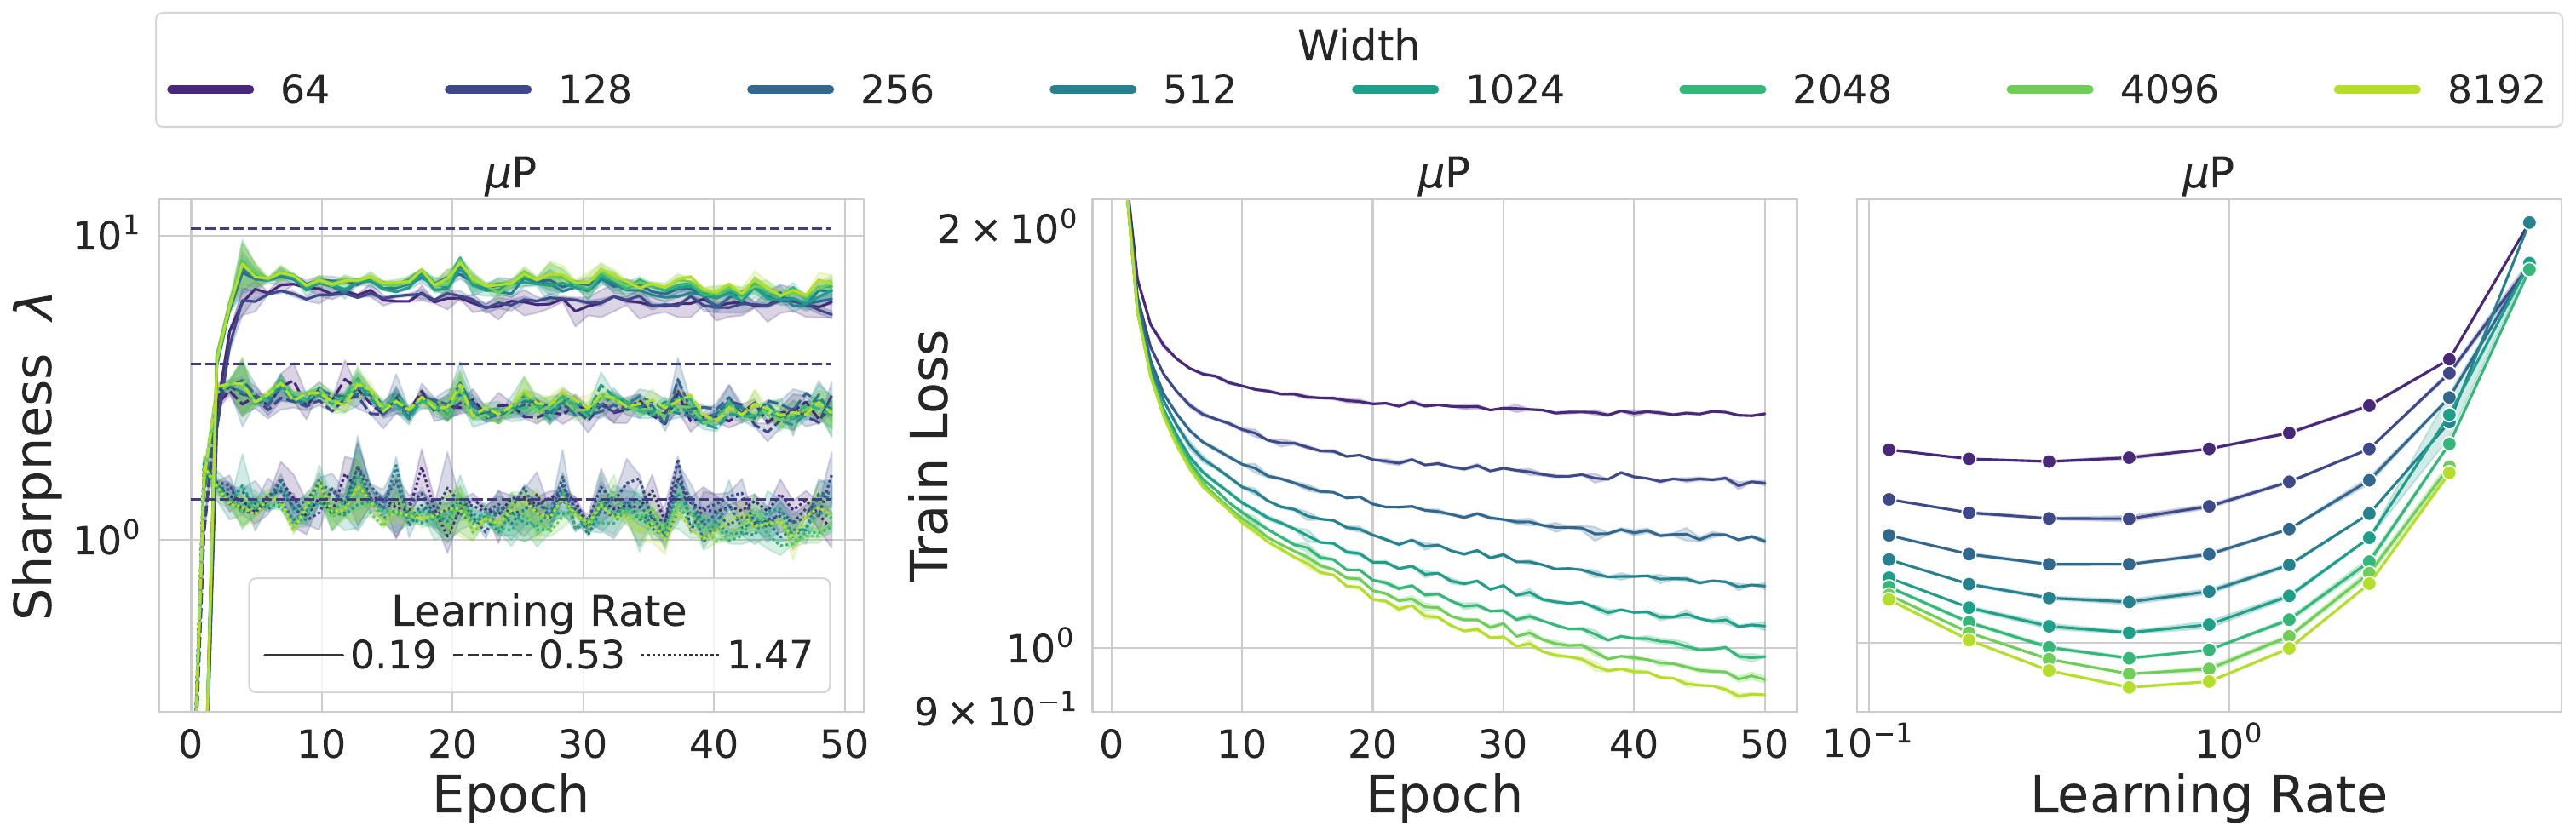 Figure 1
Depthwise Hyperparameter Transfer in Residual Networks: Dynamics and Scaling Limit
We develop a parameterization for residual networks that transfers optimal learning rates across both width and depth.
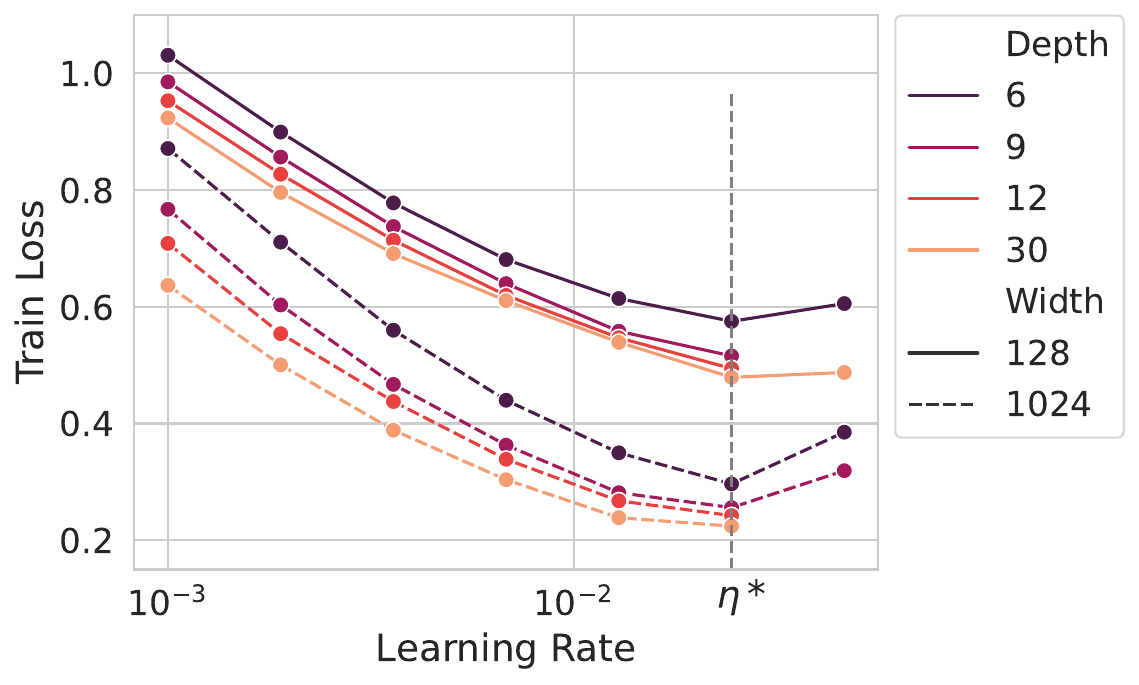 Figure 1
Dynamic Context Pruning for Efficient and Interpretable Autoregressive Transformers
We learn to prune uninformative context tokens dynamically during inference, improving transformer efficiency and interpretability while preserving model quality.
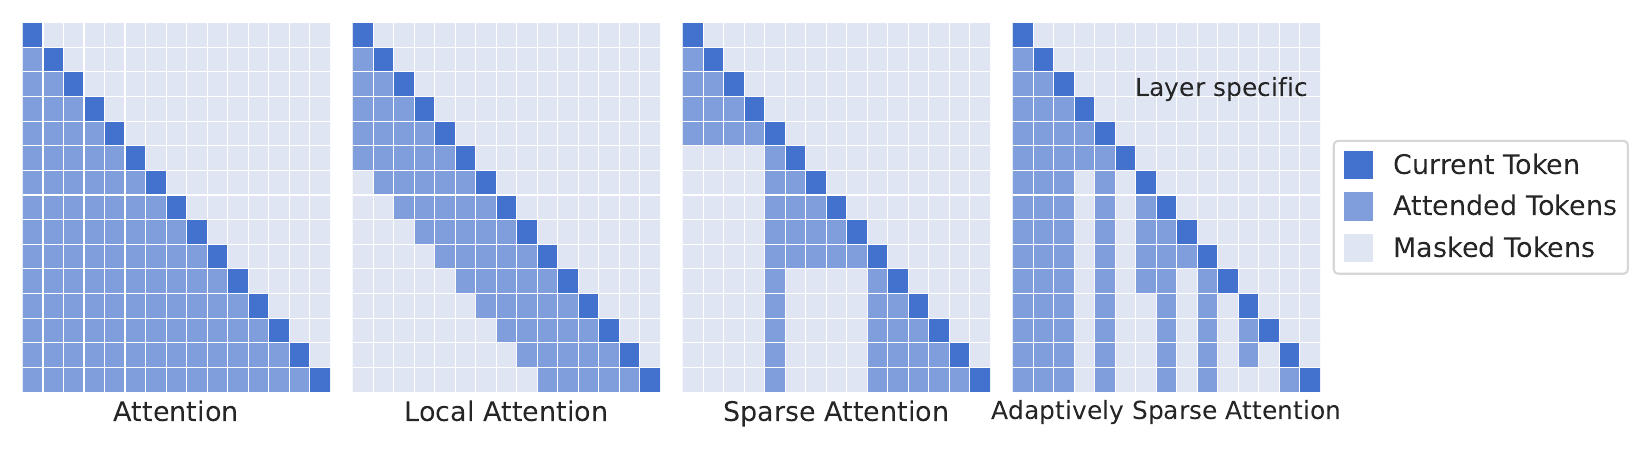 Figure 1
The Shaped Transformer: Attention Models in the Infinite Depth-and-Width Limit
We introduce shaped attention, a modification that prevents rank collapse and admits a stable infinite depth-and-width limit.
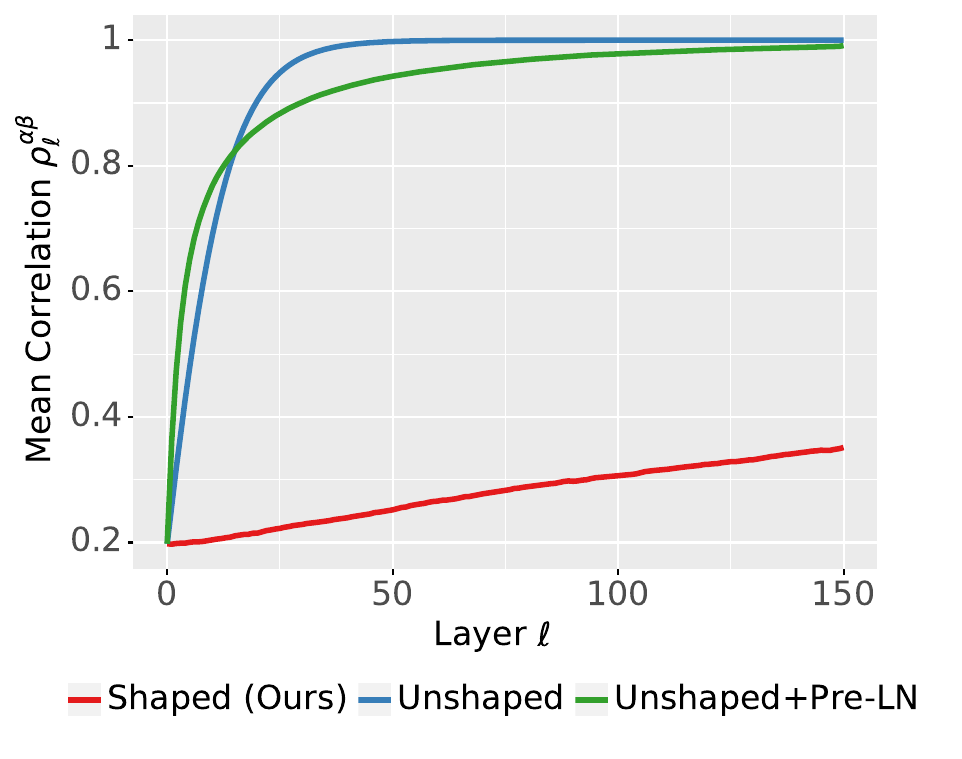
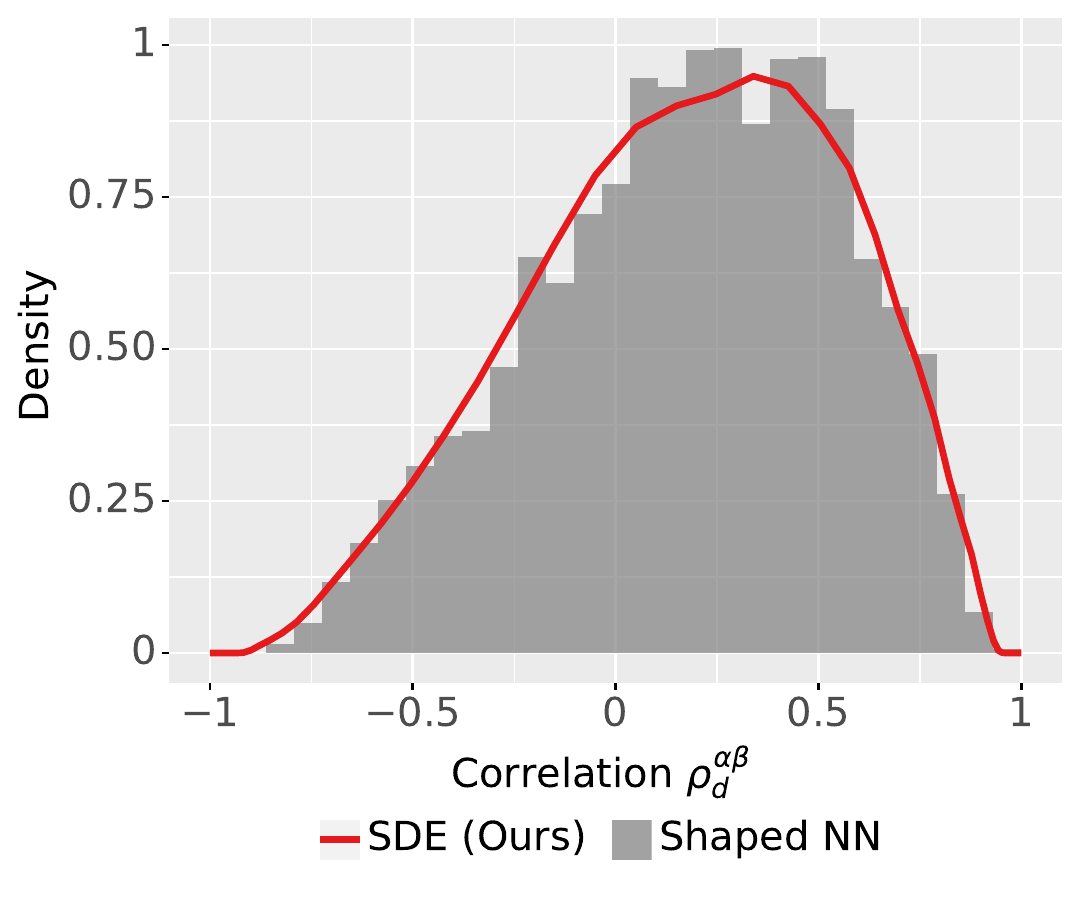 Figure 1
Signal Propagation in Transformers: Theoretical Perspectives and the Role of Rank Collapse
We connect rank collapse to vanishing query and key gradients, and derive depth-dependent residual scaling that preserves token geometry in deep Transformers.
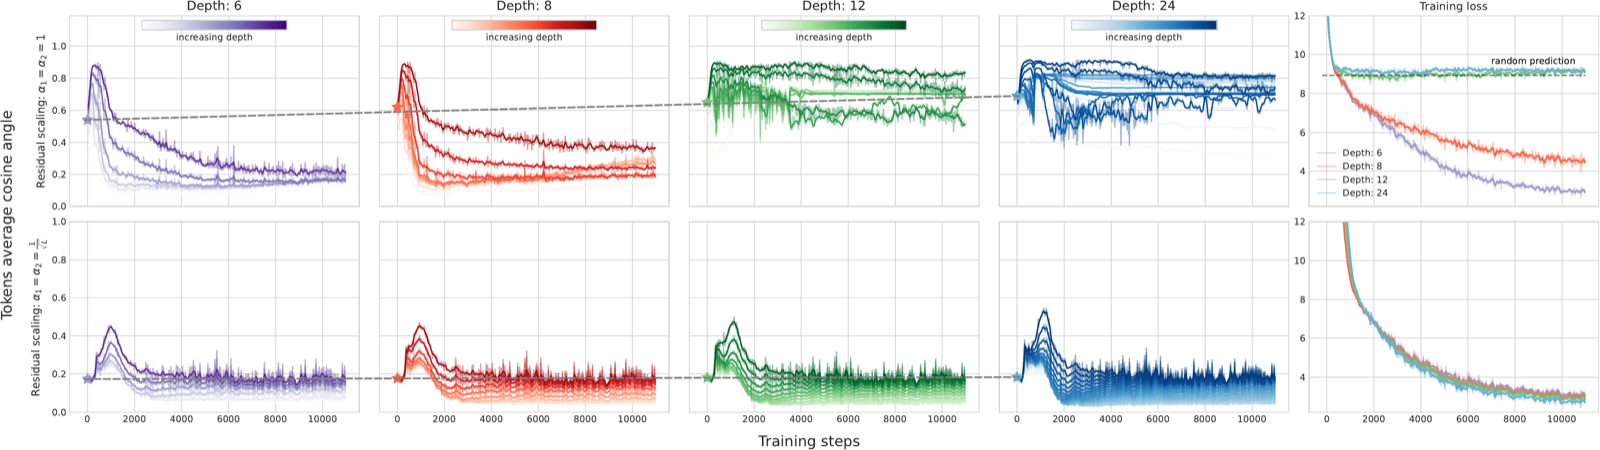 Figure 1
How Tempering Fixes Data Augmentation in Bayesian Neural Networks
We show that data augmentation creates correlated observations in Bayesian inference and that likelihood tempering corrects the resulting model misspecification.
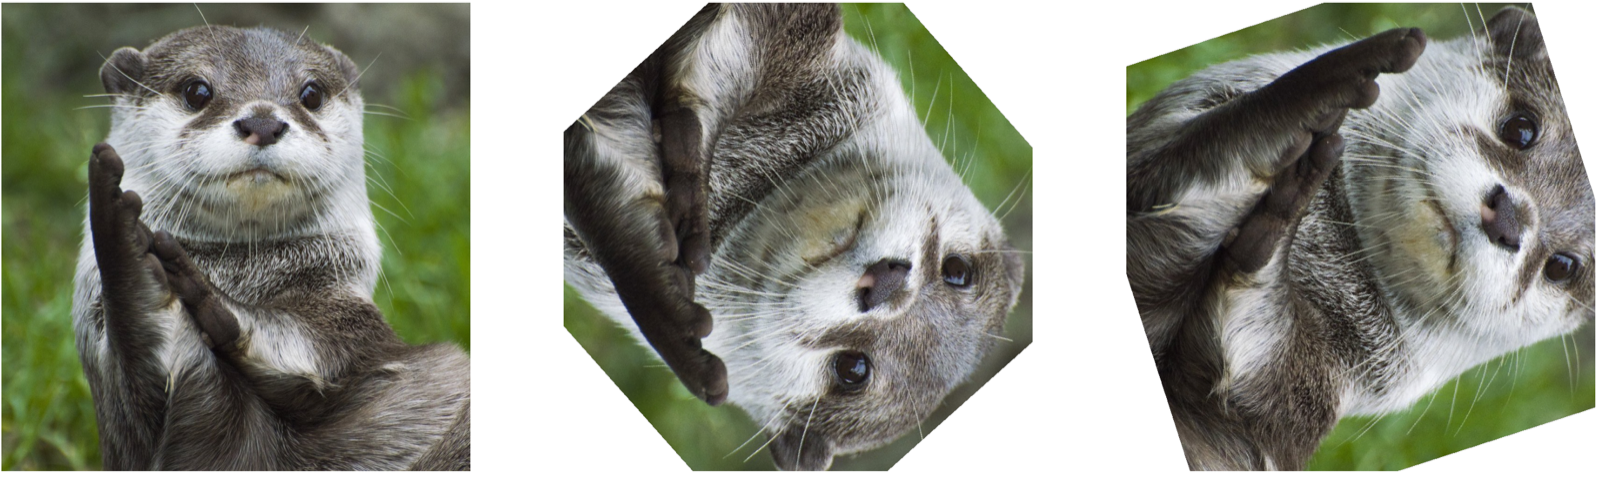 Figure 1
Precise Characterization of the Prior Predictive Distribution of Deep ReLU Networks
We derive exact finite-width predictive priors for deep linear and ReLU networks, revealing how depth and width jointly govern heavy-tailed behavior.
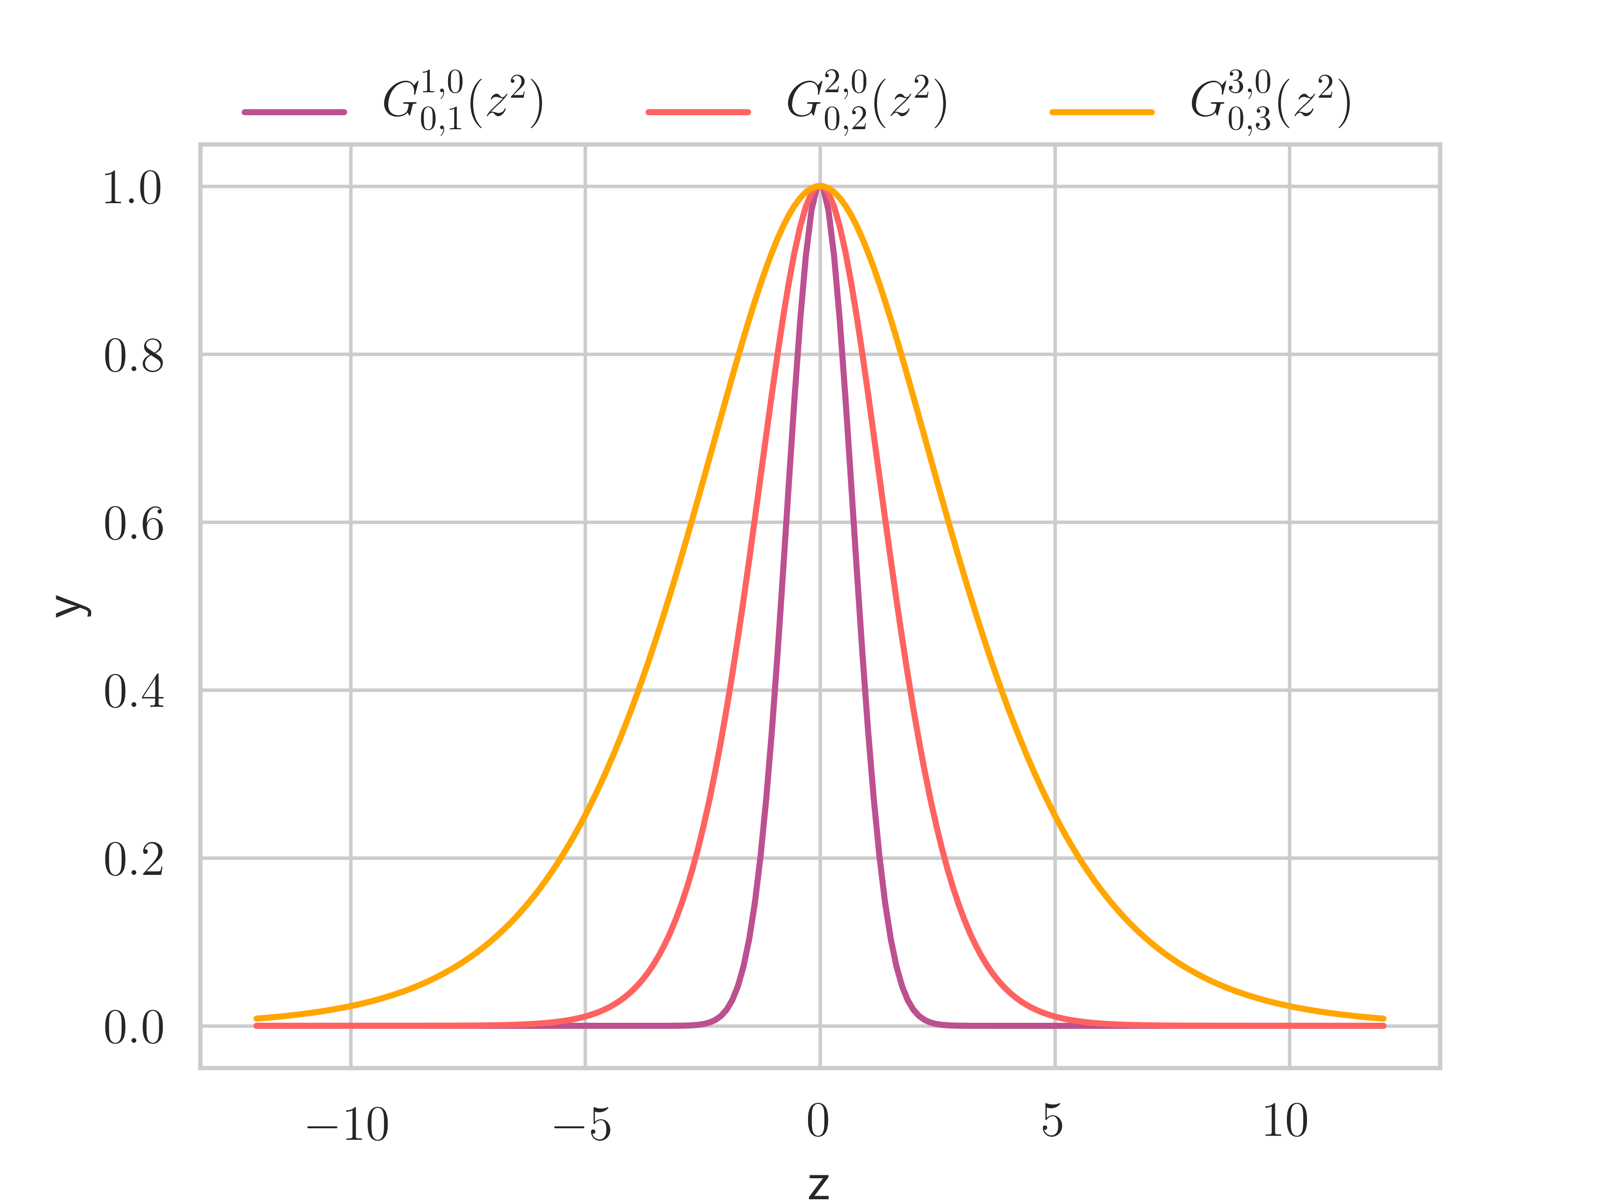
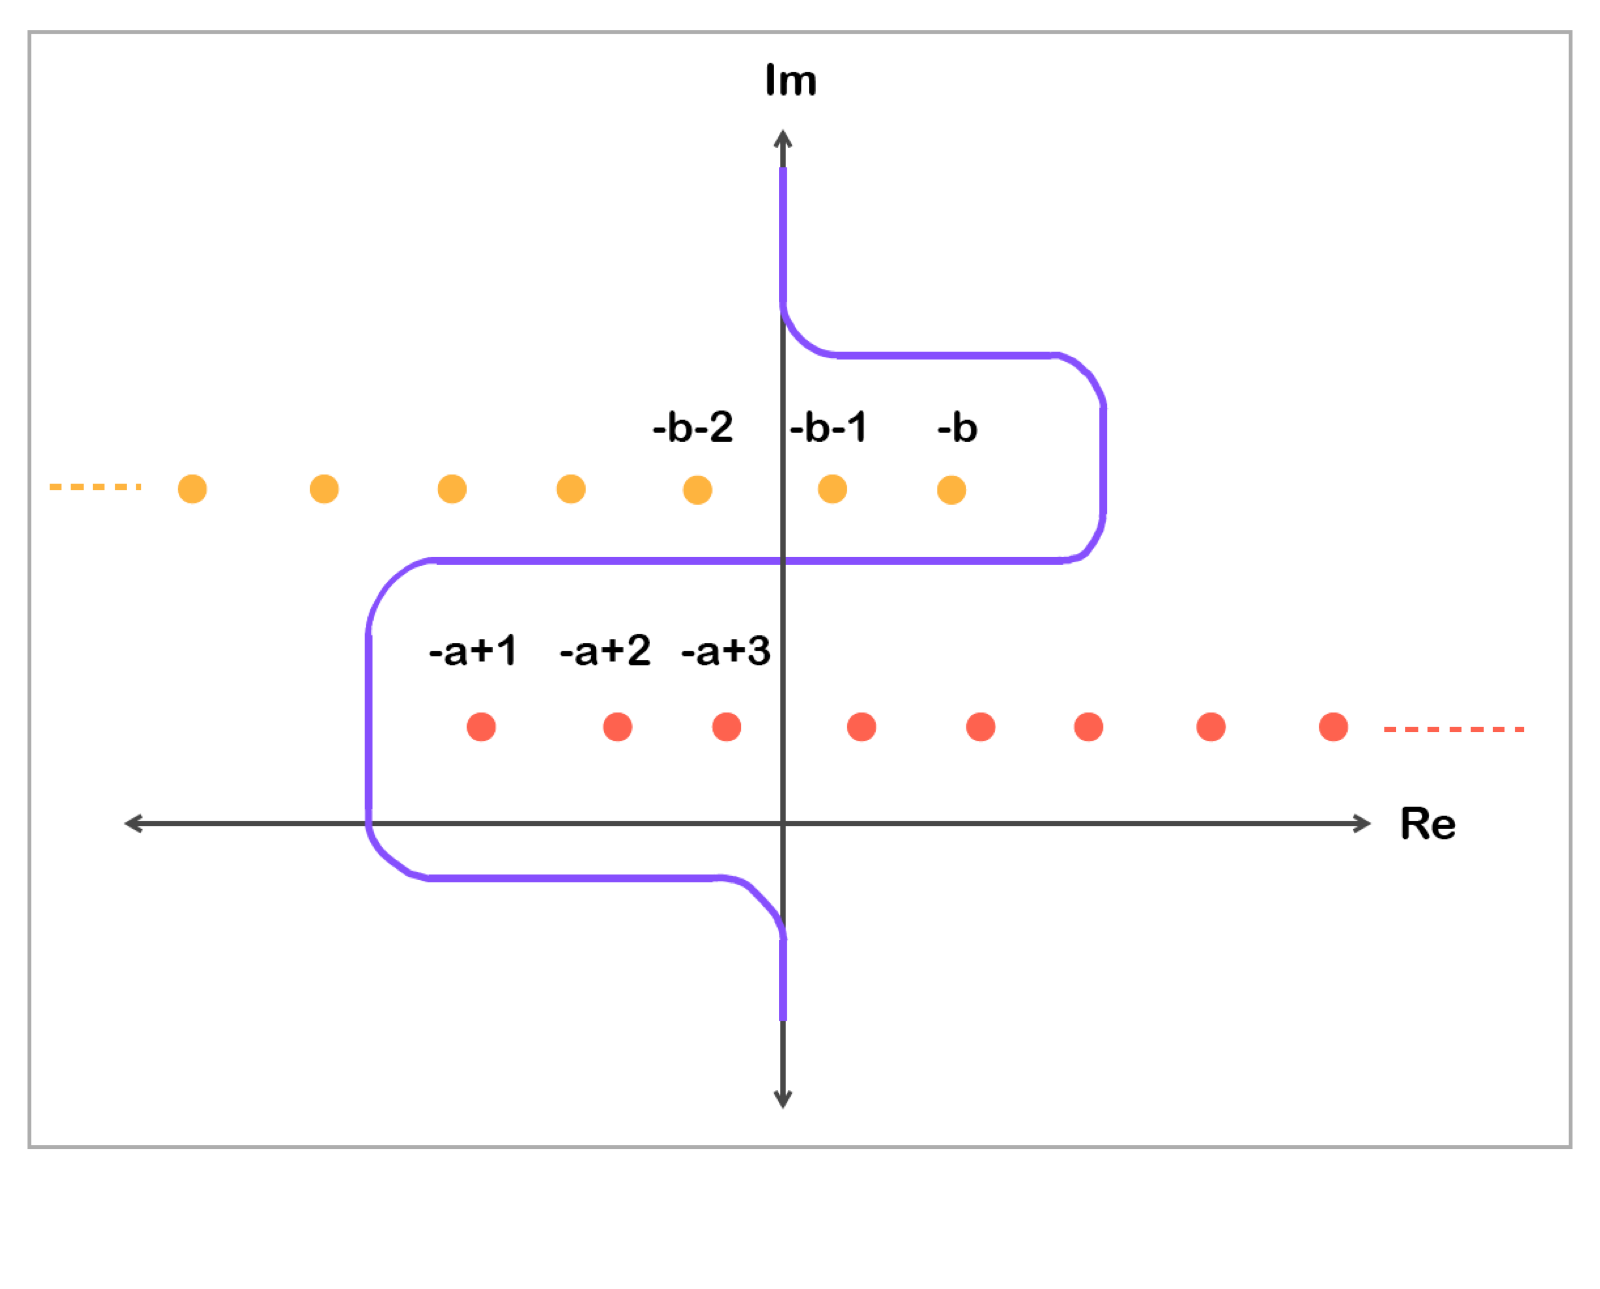 Figure 1
Archive
Additional publications
2026
2026
Universal Dynamics of Warmup Stable Decay: Understanding WSD Beyond Transformers
Preprint · HiLD & MOSS Workshops at ICML 2025 · Paper
2025
2025
2025
2024
How Good is a Single Basin?
AISTATS · Paper
2023
Disentangling Linear Mode-Connectivity
UniReps Workshop at NeurIPS · Paper
2023
2023
2021
2020
Adversarial Learning for Debiasing Knowledge Graph Embeddings
MLG Workshop at KDD · Paper
† Equal contribution.